Abstract
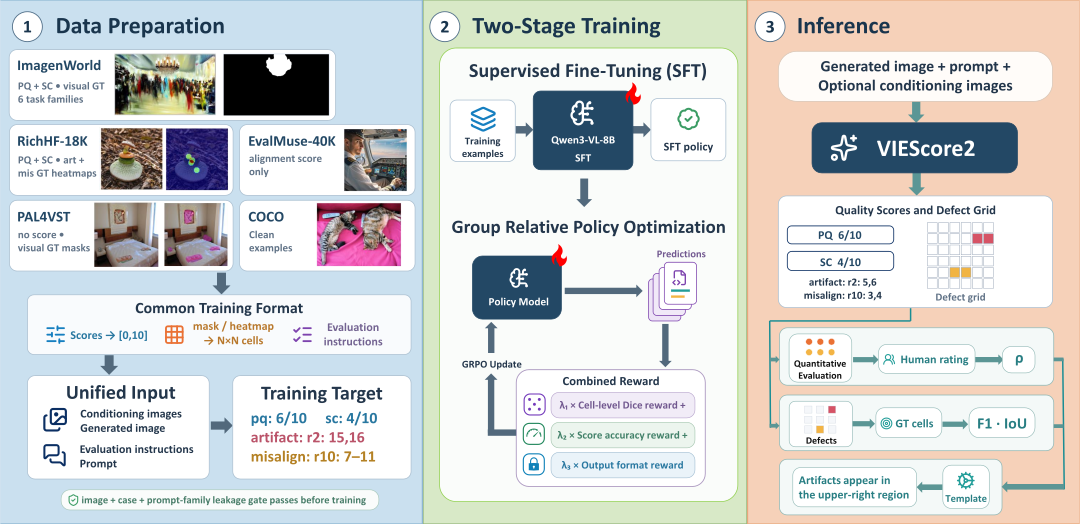
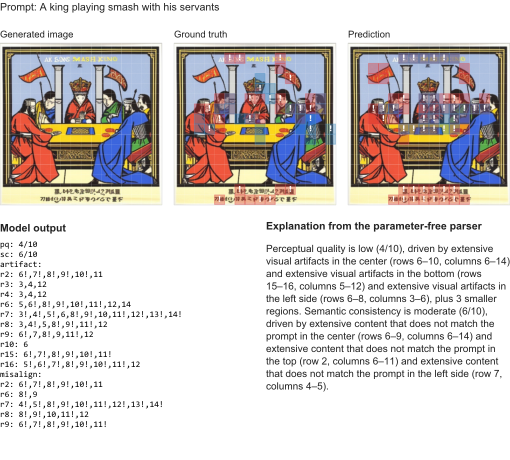
Existing synthetic image evaluators typically provide only a scalar quality score and do not identify the image regions that support it. We introduce VIEScore2, a unified evaluator for image generation and editing tasks with optional conditioning images. VIEScore2 represents an image as an N x N grid and jointly predicts quality scores and defect locations in a single model pass. Its text-native grid representation provides a common interface for heterogeneous spatial supervision and enables directly verifiable post-training objectives. We train on 38K examples spanning score-only, localization-only, and joint supervision across generation and editing tasks. Starting from supervised fine-tuning, we further apply GRPO to improve defect localization using rewards that combine cell-level Dice overlap, score accuracy, and output-format validity. A parameter-free parser converts the structured predictions into readable explanations. On the primary suite, VIEScore2 achieves an overall-score SRCC of 0.601, compared with 0.491 for Gemini-3-Flash, the strongest zero-shot general-purpose VLM baseline under matched inputs. For defect localization, VIEScore2 outperforms both general-purpose VLMs and specialized spatial evaluators on three of six benchmarks in per-image grid IoU and ranks among the top three on five, including datasets beyond its training sources.
TL;DR
Most image evaluators give you a single score but don't show where the image goes wrong. VIEScore2 is one model that scores generated and edited images and marks the defective regions on a 16×16 grid in a single pass. A simple rule-based parser then turns those predictions into a readable explanation.
Because the grid is plain text, it can be trained with SFT and then GRPO using rewards checked directly against ground truth. The result agrees with human ratings better than general-purpose VLMs such as GPT and Gemini under matched inputs, and is competitive with specialized spatial evaluators at localizing defects.
Paper: https://arxiv.org/abs/2610.00994
Code: https://github.com/TIGER-AI-Lab/VIEScore2
Model: https://huggingface.co/Allenda/VIEScore2
Project Page: https://tiger-ai-lab.github.io/VIEScore2/