Stable Diffusion
5715 readers
1 users here now
Discuss matters related to our favourite AI Art generation technology
Also see
- Stable Diffusion Art (See its sidebar for more GenAI Art comms)
- !aihorde@lemmy.dbzer0.com
Other communities
founded 3 years ago
MODERATORS
1
This is a copy of /r/stablediffusion wiki to help people who need access to that information
Howdy and welcome to r/stablediffusion! I'm u/Sandcheeze and I have collected these resources and links to help enjoy Stable Diffusion whether you are here for the first time or looking to add more customization to your image generations.
If you'd like to show support, feel free to send us kind words or check out our Discord. Donations are appreciated, but not necessary as you being a great part of the community is all we ask for.
Note: The community resources provided here are not endorsed, vetted, nor provided by Stability AI.
#Stable Diffusion
Local Installation
Active Community Repos/Forks to install on your PC and keep it local.
Online Websites
Websites with usable Stable Diffusion right in your browser. No need to install anything.
Mobile Apps
Stable Diffusion on your mobile device.
Tutorials
Learn how to improve your skills in using Stable Diffusion even if a beginner or expert.
Dream Booth
How-to train a custom model and resources on doing so.
Models
Specially trained towards certain subjects and/or styles.
Embeddings
Tokens trained on specific subjects and/or styles.
Bots
Either bots you can self-host, or bots you can use directly on various websites and services such as Discord, Reddit etc
3rd Party Plugins
SD plugins for programs such as Discord, Photoshop, Krita, Blender, Gimp, etc.
Other useful tools
- Diffusion Toolkit - Image viewer/organizer that scans your images for PNGInfo generated.
- Pixiz Morphing - Easily transition between 2 photos.
- Bulk Image Resizing Made Easy 2.0
#Community
Games
- PictionAIry : (Video|2-6 Players) - The image guessing game where AI does the drawing!
Podcasts
- This is Not An AI Art Podcast - Doug Smith talks about Ai Art and provides the prompts/workflow on his site.
Databases or Lists
- AiArtApps
- Stable Diffusion Akashic Records
- Questianon's SD Updates 1
- Questianon's SD Updates 2
- SW-Yw's Stable Diffusion Repo List
- Plonk's SD Model List (NSFW)
- Nightkall's Useful Lists
- Civitai - Website with a list of custom models.
Still updating this with more links as I collect them all here.
FAQ
How do I use Stable Diffusion?
- Check out our guides section above!
Will it run on my machine?
- Stable Diffusion requires a 4GB+ VRAM GPU to run locally. However, much beefier graphics cards (10, 20, 30 Series Nvidia Cards) will be necessary to generate high resolution or high step images. However, anyone can run it online through DreamStudio or hosting it on their own GPU compute cloud server.
- Only Nvidia cards are officially supported.
- AMD support is available here unofficially.
- Apple M1 Chip support is available here unofficially.
- Intel based Macs currently do not work with Stable Diffusion.
How do I get a website or resource added here?
*If you have a suggestion for a website or a project to add to our list, or if you would like to contribute to the wiki, please don't hesitate to reach out to us via modmail or message me.
2
3
4
5
6
7
8
9
10
11
Abstract
Variational autoencoders (VAEs) are a key part of modern text-to-image models, which generate images within their latent space. VAEs are known to disentangle the main factors of variation in the data, and color is known to be one of the most structured of these in natural images: decorrelating it yields one luminance axis and two opponent-color axes. Color should therefore be expected to emerge as a distinct factor in the VAE latent space. Yet how these latent spaces represent color remains largely unexplored. In this work, we show that the VAEs of text-to-image models share a color subspace aligned with brightness and opponent-colors. Through a linear approximation of the encoder and targeted latent steering, we find this subspace consistently across a broad range of VAEs, from SD1.5 to FLUX.2 and Z-Image. Building on this characterization, we propose three applications: ColorTuning, which achieves state-of-the-art in precise numerical color generation on the fine-grained CSS3/X11 system of GenColorBench, saturation control, to adjust the global chromatic intensity, and color transfer, to change the palette to match a reference. The code and models are publicly available at this https URL
Paper: https://arxiv.org/abs/2610.07072
Code: https://github.com/julian075/Color_Subspace
Project Page: https://julian075.github.io/Color_Subspace/


12
13
14
15
16
17
18
19
20
21
22
Abstract
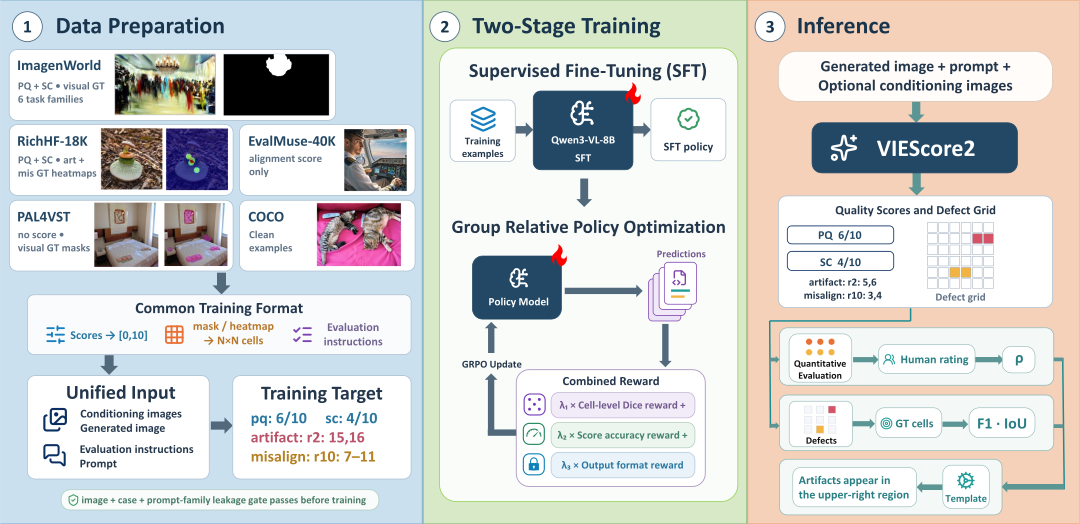
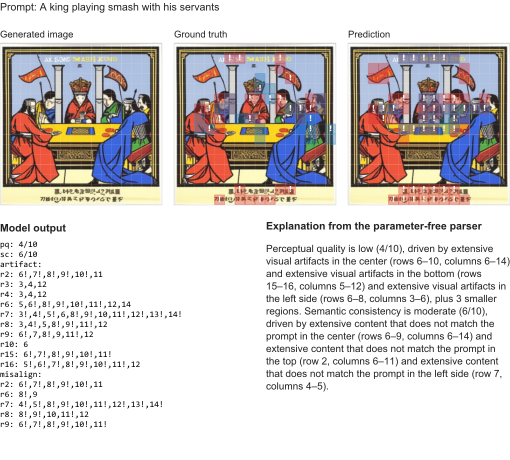
Existing synthetic image evaluators typically provide only a scalar quality score and do not identify the image regions that support it. We introduce VIEScore2, a unified evaluator for image generation and editing tasks with optional conditioning images. VIEScore2 represents an image as an N x N grid and jointly predicts quality scores and defect locations in a single model pass. Its text-native grid representation provides a common interface for heterogeneous spatial supervision and enables directly verifiable post-training objectives. We train on 38K examples spanning score-only, localization-only, and joint supervision across generation and editing tasks. Starting from supervised fine-tuning, we further apply GRPO to improve defect localization using rewards that combine cell-level Dice overlap, score accuracy, and output-format validity. A parameter-free parser converts the structured predictions into readable explanations. On the primary suite, VIEScore2 achieves an overall-score SRCC of 0.601, compared with 0.491 for Gemini-3-Flash, the strongest zero-shot general-purpose VLM baseline under matched inputs. For defect localization, VIEScore2 outperforms both general-purpose VLMs and specialized spatial evaluators on three of six benchmarks in per-image grid IoU and ranks among the top three on five, including datasets beyond its training sources.
TL;DR
Most image evaluators give you a single score but don't show where the image goes wrong. VIEScore2 is one model that scores generated and edited images and marks the defective regions on a 16×16 grid in a single pass. A simple rule-based parser then turns those predictions into a readable explanation.
Because the grid is plain text, it can be trained with SFT and then GRPO using rewards checked directly against ground truth. The result agrees with human ratings better than general-purpose VLMs such as GPT and Gemini under matched inputs, and is competitive with specialized spatial evaluators at localizing defects.
Paper: https://arxiv.org/abs/2610.00994
Code: https://github.com/TIGER-AI-Lab/VIEScore2
Model: https://huggingface.co/Allenda/VIEScore2
Project Page: https://tiger-ai-lab.github.io/VIEScore2/
23
24
25
view more: next ›